🧐 A model 660 times smaller beat 72B AIs at seeing the world like image models
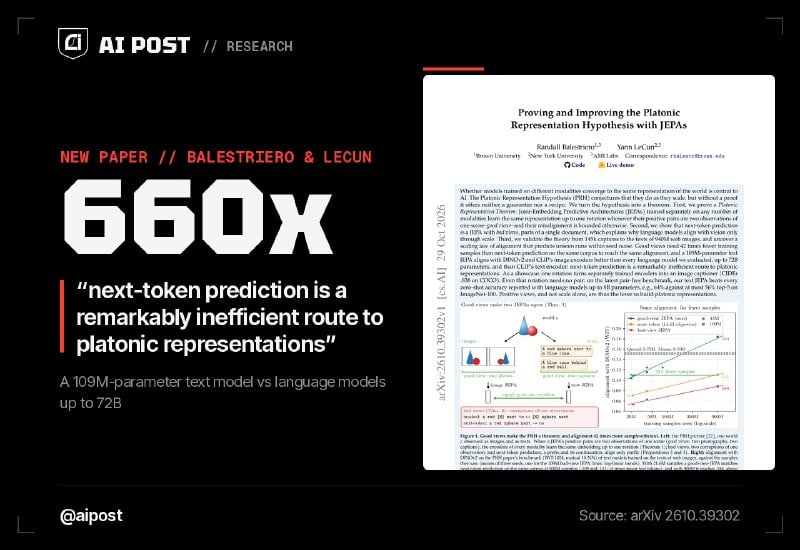
🧐 A model 660 times smaller beat 72B AIs at seeing the world like image models Yann LeCun and Randall Balestriero say the way chatbots learn, by predicting the next word, is "a remarkably inefficient route" to a shared picture of the world. AI models trained on text, images or sound may end up with the same inner picture of reality as they grow. Until now that was a guess. The new paper proves when it happens: the model must learn from two views of one scene, like a photo and its caption. Next-word prediction learns from pieces of the same document instead. On the same texts, their method got as close to image models after 21.6 million training samples as next-word prediction did after 900 million. A 109-million-parameter text model also lined up with image AIs better than every language model they tested, up to Qwen2.5-72B. The paper, from LeCun's AMI Labs, NYU and Brown, came out on October 29. @aipost 🏴