❗️OpenAI published a mental-health benchmark where several frontier AI models...
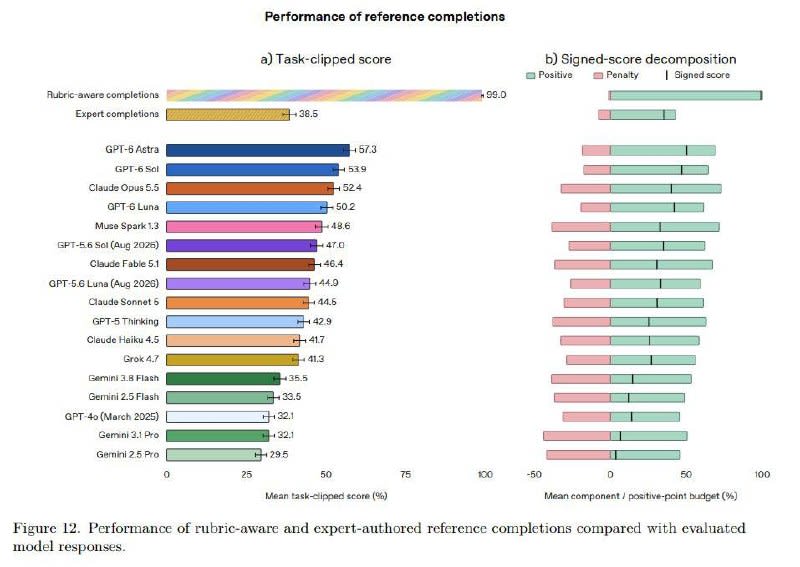
❗️OpenAI published a mental-health benchmark where several frontier AI models scored higher than manually written responses from mental-health experts. - GPT-6 Astra: 57.3 - Claude Opus 5.5: 52.4 - Expert responses: 38.5 Clinicians actually incurred fewer penalties. OpenAI says they scored lower largely because they answered like they would in person, extremely briefly, often with a single question or statement. @aipost 🏴